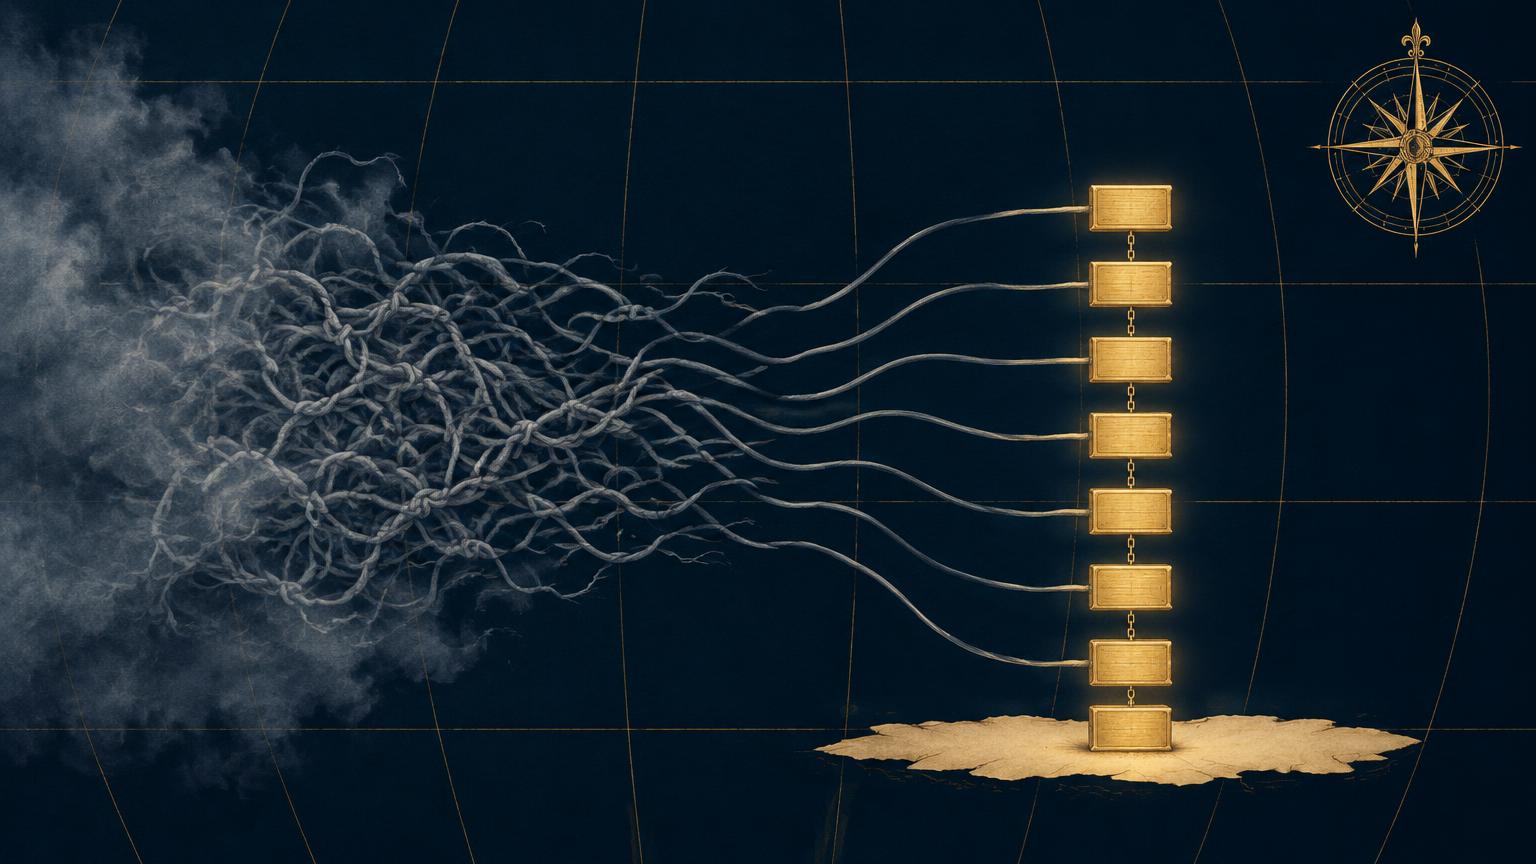
Transformation Debt, and the Record That Pays It Off
What We Mean by Transformation Debt
Transformation debt is the accumulated cost of data-transformation logic that exists only as scripts, stored procedures, spreadsheets, and the memory of the people who wrote them. Because it cannot be inspected, diffed, or reviewed, every new integration re-pays the same work, and every audit question becomes a reconstruction. It is retired when the mapping itself becomes a versioned, approved artifact with a tamper-evident record of who decided what, and why. See the full entry in the Magellan glossary.
The Debt Nobody Reports
Technical debt has a vocabulary. We talk about coupling, test coverage, dependency rot, and we have dashboards that measure all of it. Data transformation debt has none of that, which is exactly why it survives.
It is not old code. It is logic that exists only as a script, a stored procedure, and the memory of whoever wrote it. Nothing fails when it accumulates. It surfaces the day a source schema changes and nobody can say which of the last four mappings was the right one — or who decided, or what the alternative was, or why the alternative lost.
The reason it compounds is structural. Transformation logic is normally expressed in a form that cannot be inspected, diffed, or reviewed. A mapping buried in an ETL script is not an artifact. It is a side effect. And a side effect cannot be governed, so every new integration starts from zero and re-pays the same work.
There is a second cost, and it is the one that ends up on somebody's desk. When an auditor, a regulator, or a hospital's own governance committee asks *who decided that this field means that field, and on what basis*, the honest answer for most organizations is that a person decided, at some point, and the reasoning did not survive. The decision was real. The evidence is not.
Magellan is built around one idea: the mapping is the artifact. Not a byproduct of a pipeline, not a row in a spreadsheet, not a step inside a job — a versioned, governed, reproducible decision that can be inspected years after it was made.
What It Means to Make the Mapping an Artifact
It is created once, with its schemas, at import
When a mapping spreadsheet is imported, that single action creates the source schema(s), the target schema(s), and the mapping at one shared version. That shared version exists only at import. From that moment the three version independently: the source schema moves on when the upstream system changes, the target schema moves on when a downstream contract changes, and the mapping moves on when someone re-decides.
That distinction matters because the alternative — keeping everything in lockstep forever — is what forces a re-mapping every time anything shifts. Instead, a mapping version pins the exact source and target schema versions it was built against. A decision made once stays valid, and it stays *attributable* to the conditions that produced it. When the mapping has to change, it changes as a new version, and the old one is still there.
It cannot be approved out of order
There is a hard gate in the lifecycle: every schema version pinned by a mapping version must be Approved & Published before that mapping version can enter approval. Schemas approve first. The mapping approves after. Not in parallel, not as a courtesy, not as a checklist item someone is supposed to follow.
The reason is that a mapping's correctness is only meaningful relative to specific schema versions. Approving a mapping while one of its pinned schemas is still in draft means approving something whose inputs are undefined. Enforcing the order in the record — rather than in a policy document — is what turns a process into a property.
The engine advises; a person decides
The Semantic Match Engine ranks candidate field links and labels each one with the algorithm class behind it — exact_match, synonym_match, abbreviation_match, context_hierarchy, domain_equivalence, and ontology_equivalence when a governed concept layer is active — with a confidence score and a rationale.
That is not the same as automation. It is a change in what a human reviewer spends attention on. Instead of typing field pairs, a reviewer adjudicates ranked candidates, and the low-confidence band is routed deliberately: a dual-reviewer path rather than a fast approve, so the tempting shortcut is not the cheap one.
The point of naming the algorithm class is that a score alone is not defensible. *"0.94"* cannot be argued with. *"0.94, matched by context_hierarchy because both sit at patient.address.postal_code in their respective hierarchies"* can be reviewed, agreed with, or rejected — and the rejection is worth as much as the approval.
The Record Is the Return
Stopping the accumulation is the half a platform owner cares about first. The other half is what you get for it: the decisions you already made become evidence.
Every entry in the Audit & Trust Ledger carries a ULID — never a UUID — the actor and the role they held at that moment, a timestamp, the entry type, the rationale, and a SHA-256 entry_hash computed as:
entry_hash = sha256(prev_hash || payload_sha256)
Each entry's hash therefore depends on every entry before it. Change one character of a rationale written last March, and every hash after it stops matching. Insert an entry, remove one, or reorder two, and the same thing happens. There is no edit that leaves the record looking untouched.
This is what makes the ledger usable to somebody who has to sign something rather than merely read it. It is the property behind HIPAA §164.312(b), 21 CFR Part 11 §11.10(e), and the CMMC L2 §3.3 AU-family controls — audit records that are protected from modification, with retention that outlives the people who made the decisions. Magellan does not claim certification against those frameworks; it produces the artifacts a regulator or assessor asks for under them.
Decisions stay reproducible, not just recorded
A hash proves a record was not altered. It does not, by itself, let you re-derive the decision. So each entry also pins what produced it: the model version, the versioned threshold profile, and hashes of the inputs.
That is the difference between *"this is what the system decided"* and *"this is the exact ranked list the reviewer saw, and here is how to reproduce it."* An auditor can recompute the ordering an SME was shown — including years later, after both schemas have moved on — because the mapping version still points at the schema versions it actually used.
A Sample You Can Break
Every claim above is an assertion until someone can hold the thing. So we publish a sample evidence pack: eleven ledger entries covering one mapping version from spreadsheet import through both schema approvals, the engine's suggestions, three rejected links with their reasons, a release signature, publication, and a WORM seal.
The tenants, people, and identifiers are synthetic. The cryptography is not — every hash was computed from the payloads printed in the pack, and the bundled verifier re-derives them using nothing but the Python standard library. No API keys, no network, no Magellan software running.
$ python3 verify_chain.py magellan_sample_evidence_pack.json→ RESULT: CHAIN INTACT$ python3 verify_chain.py magellan_sample_evidence_pack.json --tamper→ RESULT: CHAIN BROKEN (entry #07)
The second command is the useful one. It changes a single character inside one entry's payload and reports exactly where the chain stops closing. Run it once and you have a feel for the property that no amount of policy documentation can supply.
The source-to-target mapper shows the review surface those entries describe: ranked threads, confidence, algorithm class, and a rationale you can read before you decide.
What to Take With You
If you only keep one sentence: Magellan converts transformation debt — undocumented, drifting, tribal logic — into versioned, governed, reproducible decisions, and then makes the entire decision history tamper-evident, so the past becomes an asset instead of a liability.
The practical version is a two-part test you can run against any vendor, including us:
1. Is the mapping an artifact? Can you diff it, pin it to specific schema versions, and read it without running the pipeline that uses it?
2. Can you verify the history without the vendor? If re-deriving the hashes requires their software and their database, you have a log, not evidence.
If both answers are yes, transformation debt stops compounding and your mapping history starts paying interest.
Request a demo to see the review surface with your own schemas, or read the white paper for the full architecture.
*Magellan AI Corporation — Charting every data connection.*